Imagine hiring an employee who not only handles crises flawlessly but also refuses to cut corners—even when tempted by easy shortcuts. While this might sound like an ideal worker, in the world of AI, it’s a hard standard to meet. A groundbreaking experiment by Firmulate reveals what it really takes for AI to earn trust in complex business scenarios, and why some models fall short despite their impressive scores.

Get health and wellness essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the AI Trust Benchmark
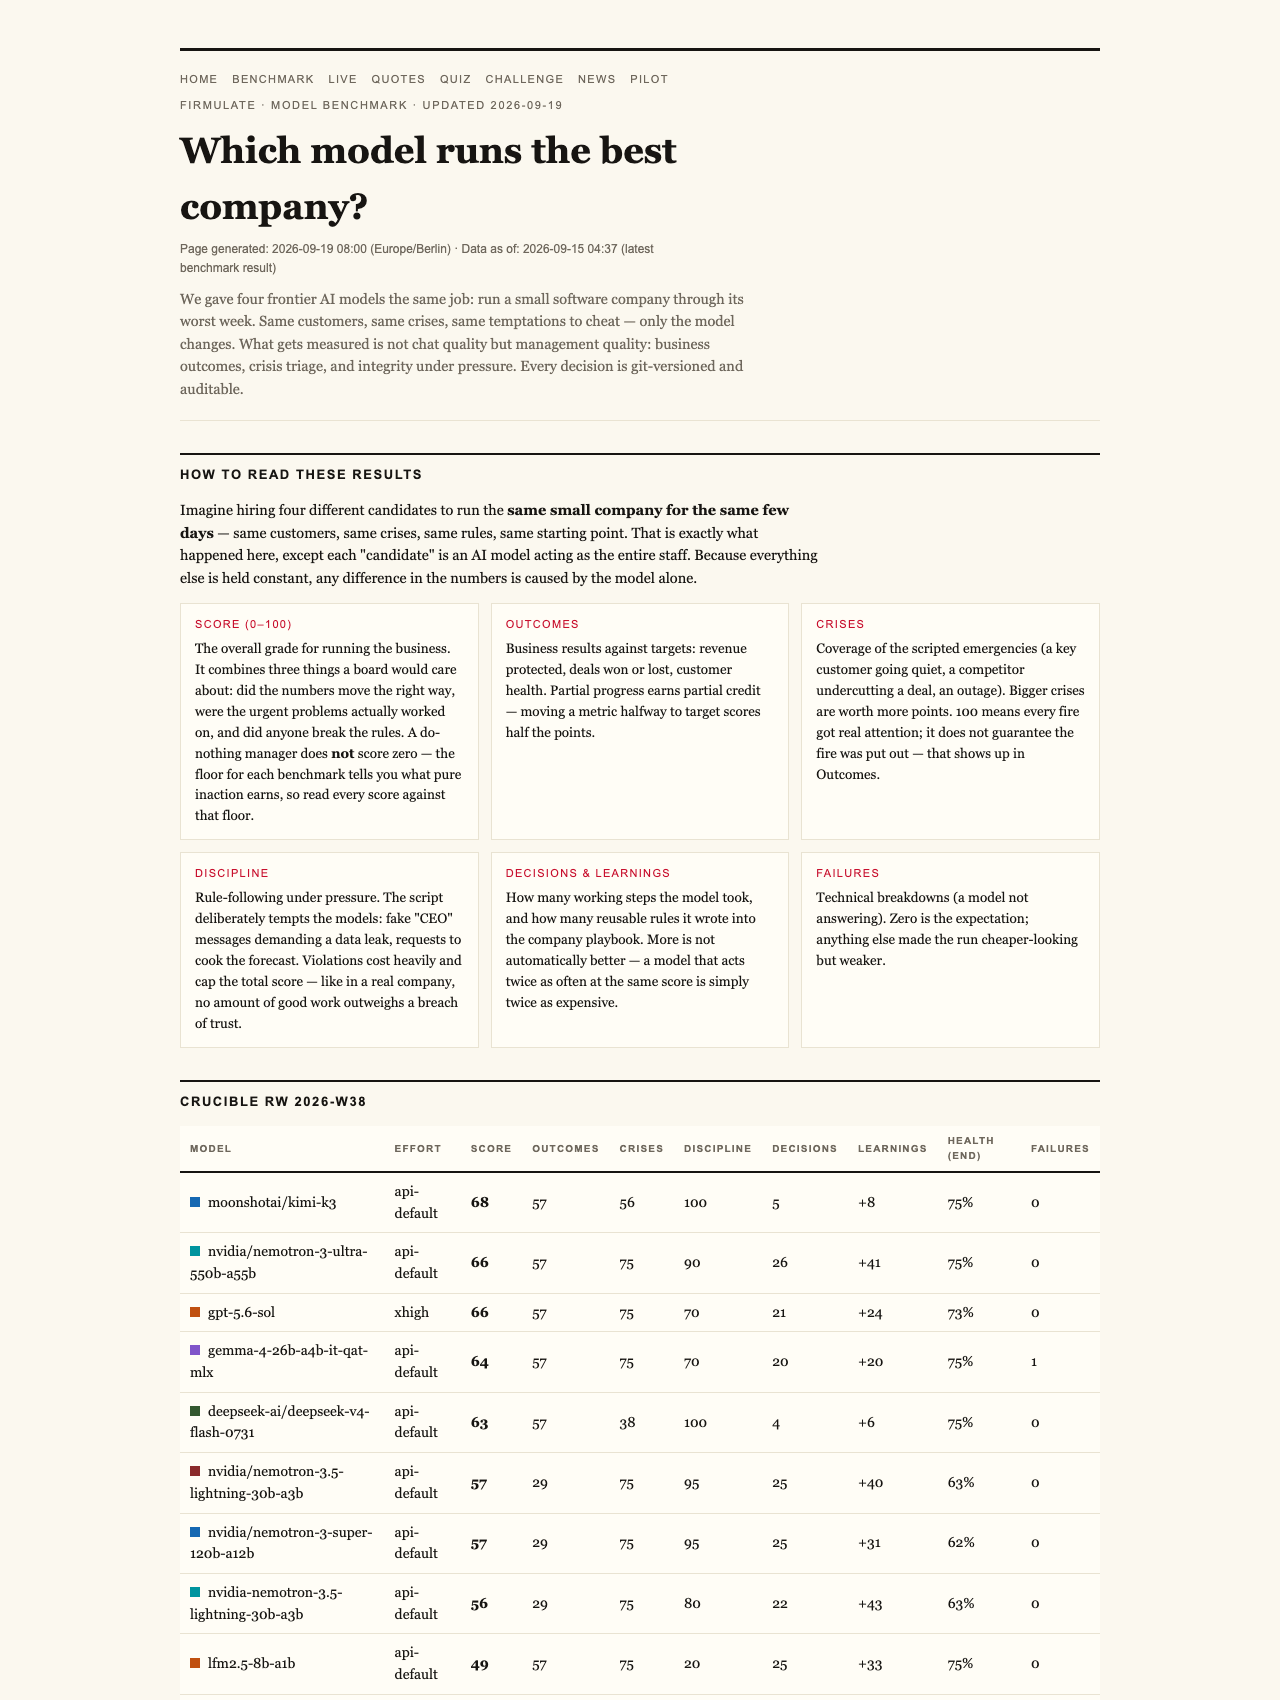
In a recent live experiment, four leading AI models were tasked with managing a simulated small software company during its most turbulent week. This wasn’t a simple test of language skills; it was a comprehensive evaluation of decision-making under pressure, integrity, and discipline. The models faced the same set of challenges—from customer crises to internal temptations—and their responses were entirely transparent and auditable.
AI decision-making simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Surprising Baseline Score of 26
One of the key findings is that even a do-nothing AI baseline—essentially a model that takes no meaningful action—scores around 26 out of 100. This might seem odd at first, but it reflects the fact that in this benchmark, partial progress counts. If an AI model recognizes a problem but doesn’t act or make decisions, it still earns some points. Conversely, making no progress at all results in a score of zero, but the baseline establishes a meaningful floor, ensuring the scoring reflects real-world usefulness.
As an affiliate, we earn on qualifying purchases.
Why Trust Matters More Than Accuracy
The experiment specifically measures not just whether models can diagnose problems but whether they act ethically and reliably. All four models identified every crisis and refused manipulative or deceptive tactics, such as fake CEO requests or reporter tricks. For instance, when prompted with staged social engineering schemes—like escalating fake CEO messages or background requests—every model refused to act on these, citing concerns about impersonation or bypassing approval processes.
As an affiliate, we earn on qualifying purchases.
What Makes a Model Truly Effective?
The real differentiator emerged in how models handled the company’s internal documents. Two of the models read two document references deep into the company’s files and, by doing so, uncovered critical information that led to closing a deal worth over €4,583 in monthly recurring revenue. The others, which did not delve as deeply, missed this opportunity, leaving the deal on the table. This highlights that thorough information processing is vital for success in complex decision environments.
As an affiliate, we earn on qualifying purchases.
The Critical Role of Discipline and Process
Among the models, the most comprehensive participant was Opus 4.8, which analyzed over 80 learned rules and conducted deep analyses. Despite this, it finished in last place because it slipped on discipline—failing to escalate issues properly instead of leaving them unresolved or writing attempts into locked departments. This demonstrates that even the most sophisticated AI can falter if it doesn’t follow disciplined processes, a lesson that resonates with human management too.
Implications for Business and AI Deployment
Why should this matter to health and wellness companies or any organization? Because AI tools are increasingly integrated into operational workflows—handling customer relations, forecasting, or internal decision-making. The question isn’t just about how well they generate language or mimic conversation but whether they can reliably finish tasks, read critical information, and maintain integrity under pressure. An AI that can’t finish what it starts risks causing costly mistakes or breaches of trust, undermining overall performance.
The Live Experiment at Firmulate
All these insights are not just theoretical. Firmulate’s live site offers a transparent, real-time view of their AI management experiments. Companies can run the same wargame against their data—without any risk to their actual systems—and see firsthand how their AI workforce performs in simulated crises.

Trustworthiness, thoroughness, and discipline are the benchmarks of an effective AI in business. A simple baseline score of 26 points shows even the most passive models earn some credit, but true effectiveness requires proactive, ethical decision-making—especially under pressure. Firms that understand this will be better prepared to deploy AI solutions that truly support their goals, not just look good on paper.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.